indra
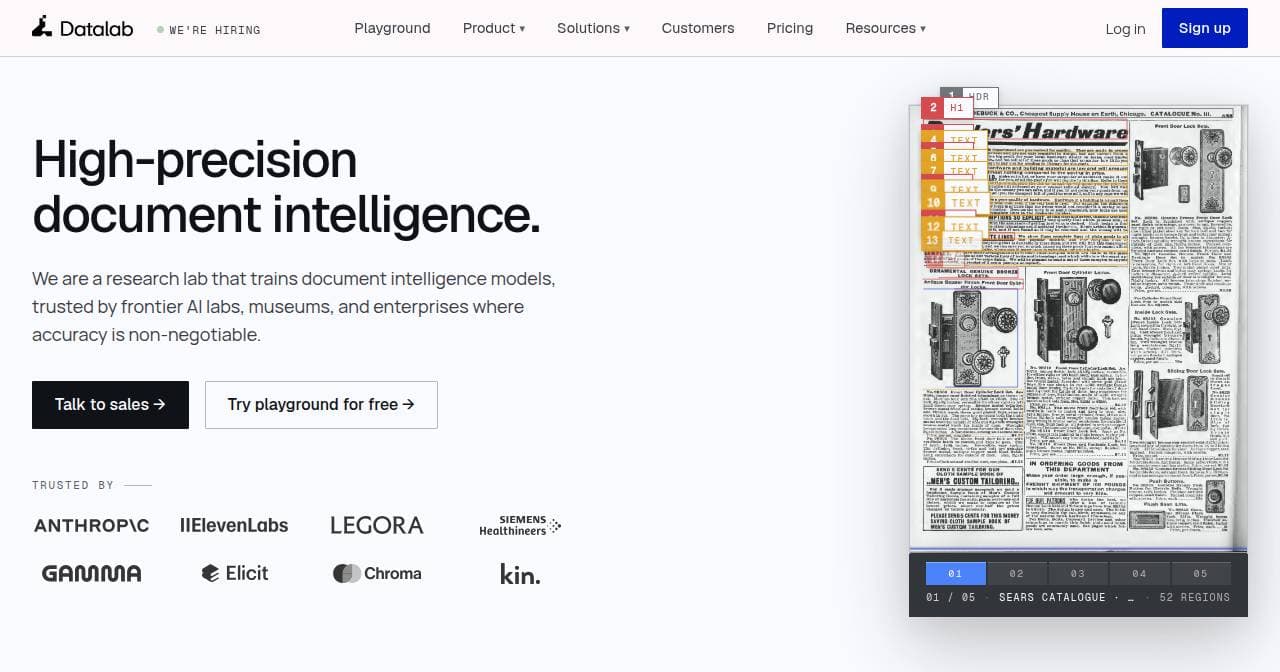
Transform unstructured content into precise, production-ready data. Datalab equips organizations to feed AI systems and automate workflows with dependable, audit-ready data.
indra launched on 13 October 2026. It ranked #112 on Daily Launch on 30 October 2026 with a Launch Score of 18, from +58 stars today on GitHub. It moved down 27 places from the day before.
What is indra?
Indra OCR is a 1M-parameter OCR model that runs on CPU. It turns PDFs and images into markdown, text, or JSON with boxes, and it reads handwriting, 80+ languages, and pages at any angle. Indra OCR is built for speed on CPUs. When you need the highest accuracy, on handwriting, math, complex tables and degraded scans, our managed platform runs Chandra, our state of the art OCR model, with zero data retention by default, SOC 2 Type 2, and custom BAAs.
From its README on GitHub
indra is a repo by datalab-to on GitHub. It is written in Python and released under the Apache-2.0 license.
How to get indra
pip install indra-ocrFrom its README on GitHub
More steps and the source are in its repository on GitHub.
Screenshot of datalab.to
In its own words
Fast CPU OCR: line detection, CTC recognition, reading order, markdown
From its GitHub repository
1M param OCR model - runs on CPU, 15x faster than tesseract, close to 1B+ param models in accuracy
From its GitHub repository