Parsimony
An open-source benchmark of how much code AI models add.
Parsimony launched on 13 October 2026. It ranked #54 on Daily Launch on 14 October 2026 with a Launch Score of 43, from 72 points on Show HN. It was new in the ranking that day.
What is Parsimony?
Existing benchmarks measure solve rate and token output/cost, but don't punish excess code, which makes a codebase harder to work with in the long term. I wanted to measure this since it matters most for long-term projects. Method: it takes the patches that benchmarks already publish (DeepSWE, SWE-bench Verified, SWE-bench Live) and counts "coding units": syntax elements like statements, calls, names and literals. I didn't use lines of code, so cramming code isn't rewarded. Deleted code is subtracted, so it measures net units.
From its Hacker News post
Parsimony is a launch on Show HN.
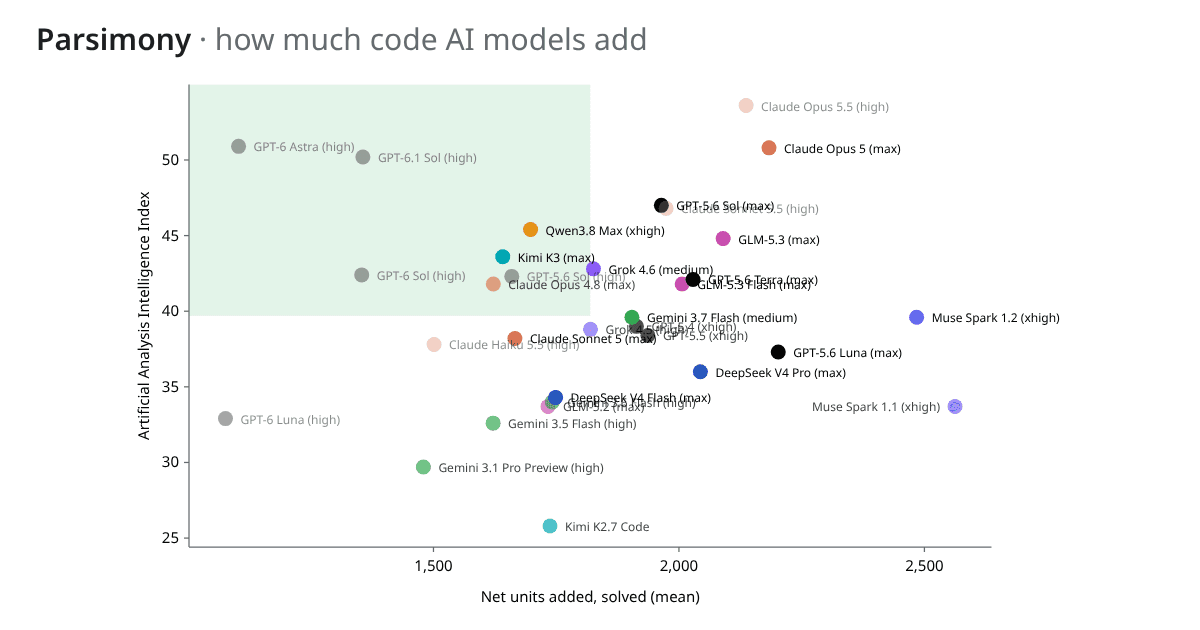
Image from parsimony.lasu.dev
Launch timeline
Launch Score, last 7 days
Ranked on one day so far: 43 of 100 on 14 October.